A technical SEO audit in one evening: our working checklist
A full SEO audit from an agency can take two weeks and fill a 60-page PDF. But 80% of the technical problems we find on websites are visible in one evening with a terminal and Search Console. Here is our checklist, step by step, no filler.
 Mirodil OrtiqovBackend developer
I'm a backend developer. For a long time SEO was something “the marketing people” did while I wrote APIs in Django. Then we started digging into why a media portal's pages were indexing so badly, and it turned out nearly every cause lived in the code. Including my code.
Since then I've run the same list on every site that lands on our desk. It doesn't replace an SEO specialist's work on queries and content. It answers a simpler question: can a search engine read this site properly at all?
The order for the evening
I split the evening into blocks and go strictly top to bottom. If the site returns a 500 to the crawler at step one, there's no point measuring speed.
- Indexing, 30 minutes. robots.txt, sitemap, status codes, redirects between http/https and www.
- What the crawler sees, 30 minutes. Is the content in the initial HTML, or does it only appear after JavaScript runs?
- Meta and markup, 40 minutes. title, description, canonical, headings, Open Graph, structured data.
- Speed, 30 minutes. PageSpeed Insights and the Core Web Vitals report in Search Console.
- The site's history, 20 minutes. Old URLs after a redesign, 404s in Search Console.
- Task list, 20 minutes. Every finding becomes a task with a priority.
The tools are free: curl, Google Search Console, Yandex Webmaster, PageSpeed Insights, Rich Results Test. For a small site, the free version of Screaming Frog with its 500-URL limit is enough.
Indexing: robots, sitemap, status codes
The first thing I do is look at what the server returns, through the crawler's eyes. The browser gets in the way here: it follows redirects on its own, caches, and hides the details.
curl -sI http://example.uz/ | grep -iE "^(HTTP|location)"
curl -sI https://www.example.uz/ | grep -iE "^(HTTP|location)"
curl -s https://example.uz/robots.txt
curl -s https://example.uz/sitemap.xml | head -c 600
curl -sI https://example.uz/takoy-stranitsy-net | head -n 1
The last line catches a classic SPA problem: a page that doesn't exist answers 200 and shows “Page not found” as text. To Google that's a soft 404, and hundreds of them can pile up in the index.
- http and www lead to a single version of the site with one 301, no chains
- robots.txt exists, doesn't block the whole site and points to the sitemap
- Service paths (
/api/, the admin, search with parameters) are blocked in robots.txt - sitemap.xml returns 200, is valid and contains real pages, not just the homepage
- The sitemap has no URLs that return 301 or 404 or are marked noindex
- A non-existent URL returns a real 404, not a 200
- The site is verified in Search Console and Yandex Webmaster, and the sitemap is submitted
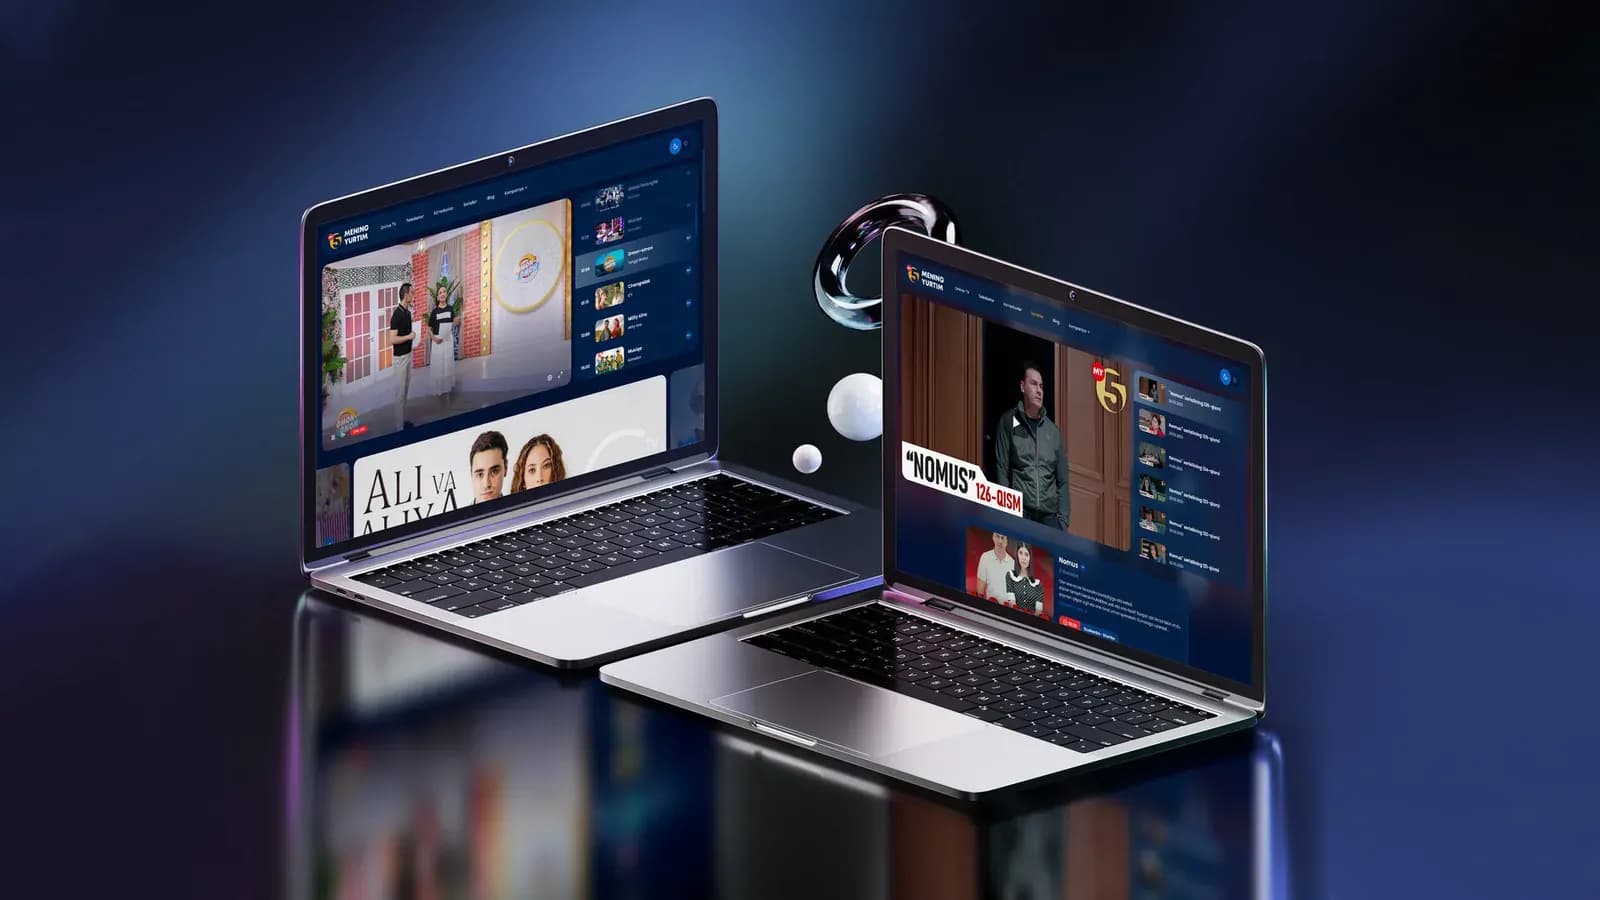
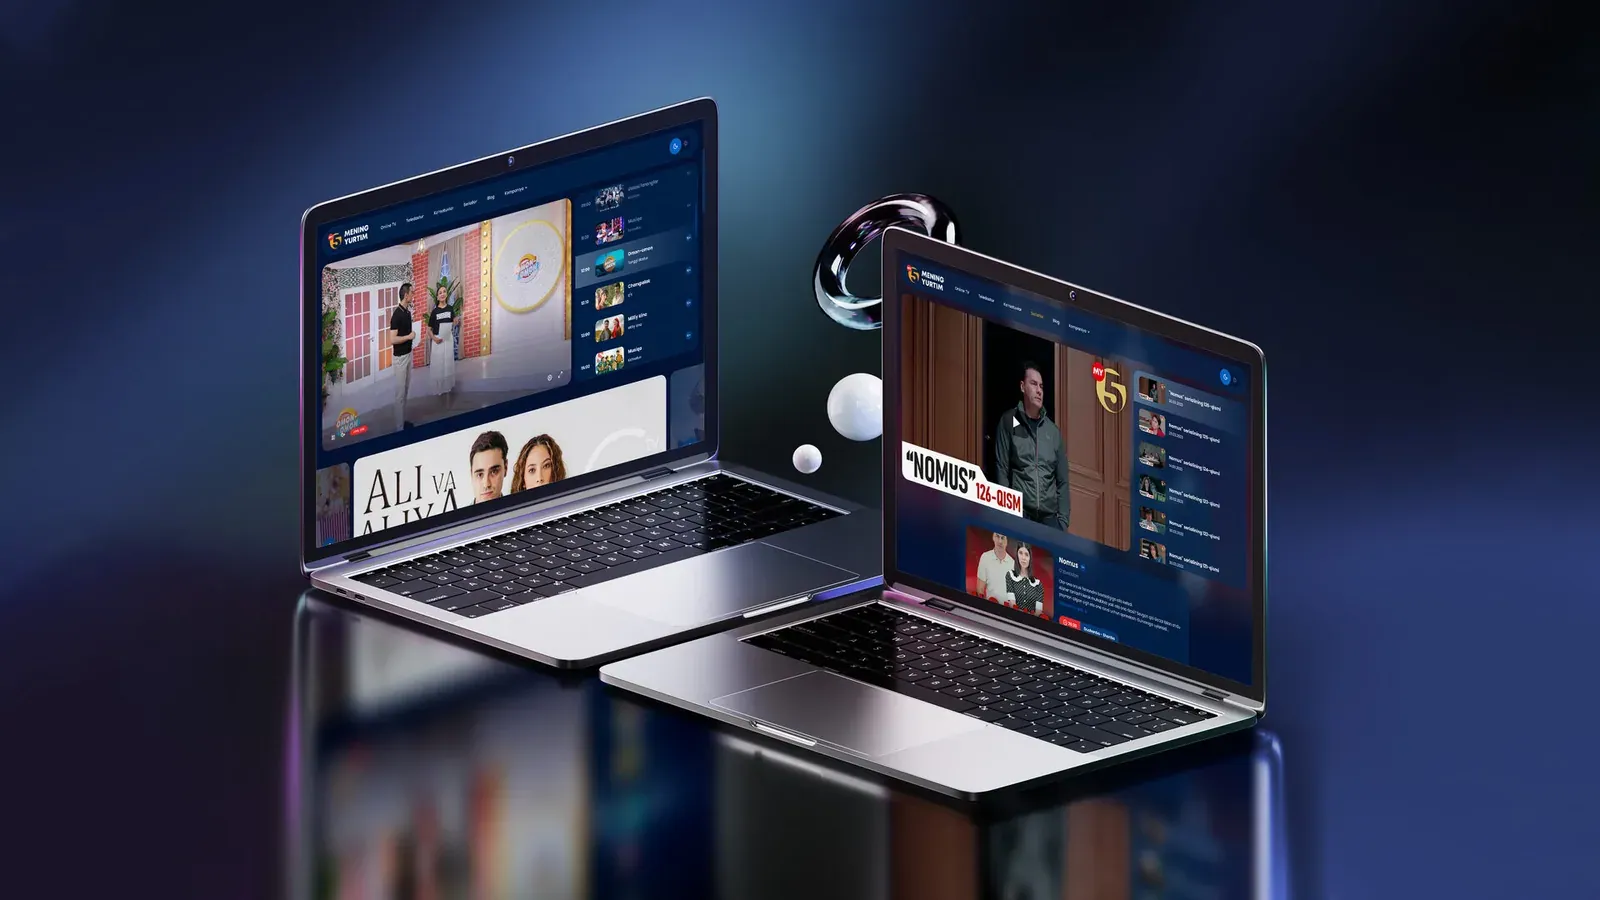
On My5, the portal of the Mening Yurtim TV channel that we've maintained since 2023, the audit showed that /sitemap.xml was returning 404. Search engines only found what they could reach by following links. For a site with hundreds of pages of series, shows and articles, that's a direct loss. We built a dynamic sitemap right inside Nuxt, crawling the API with a one-hour cache, and added a robots.txt with Disallow: /api/.
What the crawler sees without JavaScript
This is the most important block for sites built on Vue or React. Google can render JavaScript, but it does so with a delay and not always. Yandex handles it worse. Telegram and Facebook don't run JavaScript at all when building link previews.
The check is simple: open “View page source” (not the inspector, the actual source) and search it for some text from the first screen.
In the same place I found something only indirectly related to SEO, but impossible to ignore. The Nuxt proxy passed paths to Django without a trailing slash, and Django with APPEND_SLASH answered with a 301. Every API request took a double round trip, and a POST turned into a GET after the 301. From the outside it just looked like “the site is a bit slow”.
- First-screen text, the main heading and links are present in the initial HTML
- Menus and links to inner pages are plain
<a href>elements, not click handlers - Internal links point straight to the final URL with no redirect (watch the slashes)
- Catalogue pagination and filters are reachable via links, not only via a “Load more” button
Meta, headings, markup
Everything here is boring and everything matters. I go through 5–10 typical pages: the homepage, a section, a product card, an article, contacts.
- Each page has its own title and description, no duplicate “Home | Site”
- A canonical tag exists, is absolute and points to the page itself (or to the original for duplicates)
- One
<h1>per page; section headings are<h2>and below - og:title, og:description and og:image are present, and og:image is an absolute URL
- Structured data passes the Rich Results Test without errors
- A multilingual site has hreflang, and it matches the canonical
The <h1> situation on My5 was fun as well: section headings and small captions were all marked up as h1, and the homepage ended up with more than ten of them. Nobody notices visually, but the search engine loses track of what the page is about.
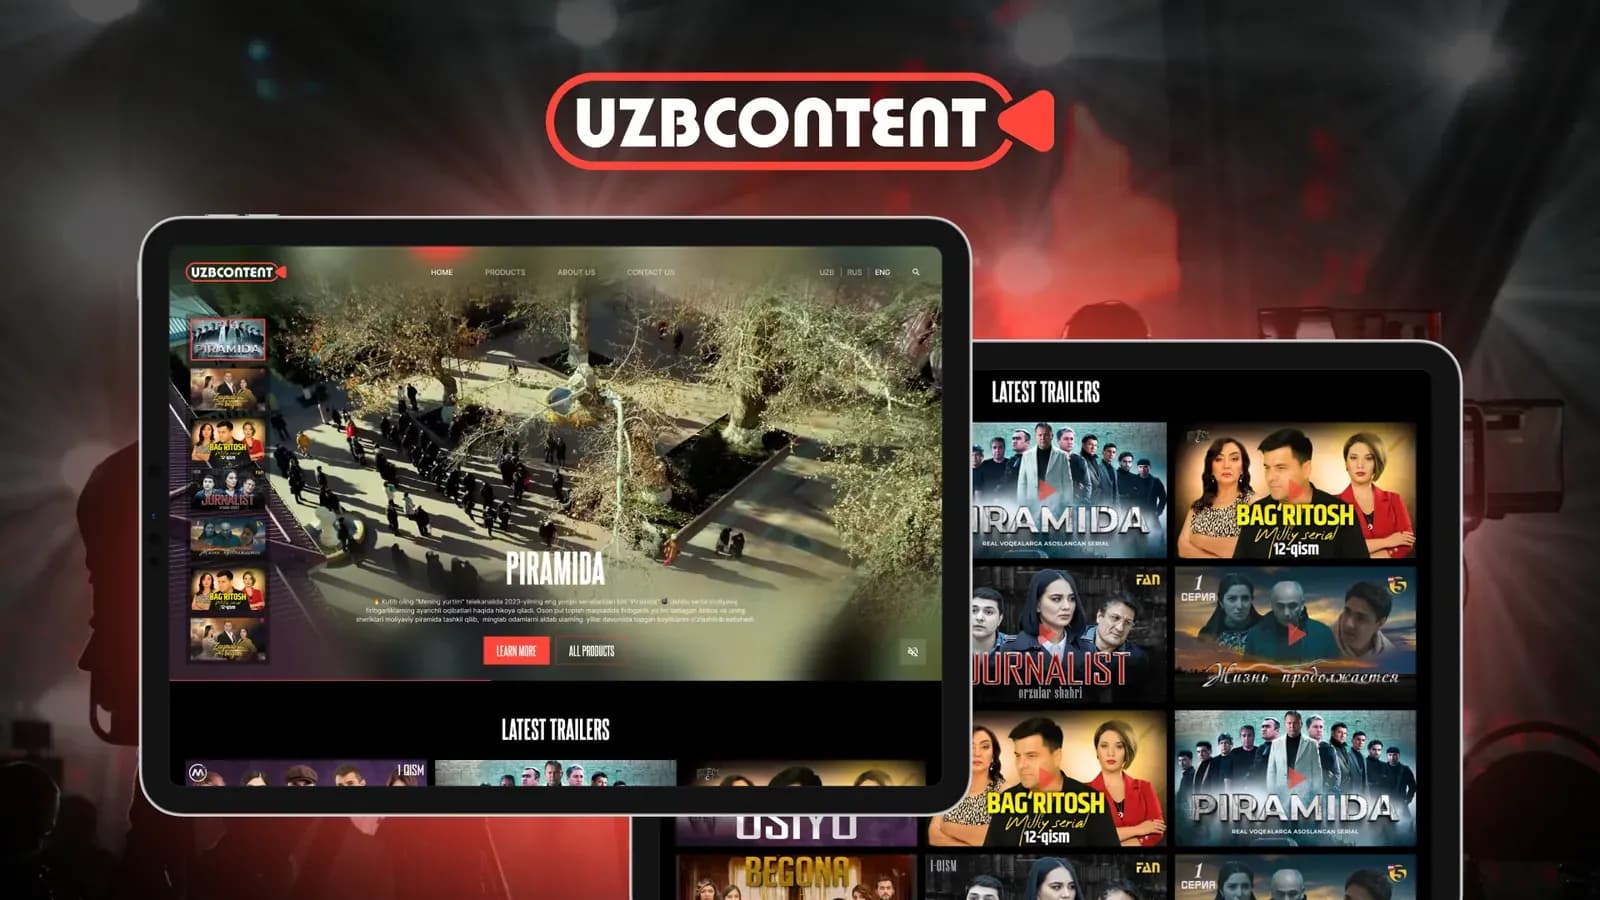
A separate word on markup. For UZBCONTENT, a showcase of Uzbek TV series for international buyers, the trailers are the whole point of the site. A site like that benefits from VideoObject markup on its trailers, which gives the videos a chance to show up in Google's video results. Buyers there search in English, and a series with a thumbnail and duration in the results looks far more convincing than a bare link. Shahzod covered hreflang and multilingual sites in detail in his post on websites in three languages.
Speed and Core Web Vitals
I don't chase a perfect 100 in PageSpeed. I look at the field data in Search Console first: that's real users, not a simulation. Since March 2024 INP has replaced FID there, and on sites with heavy sliders it's often red.
- LCP on mobile under 2.5 seconds in field data
- INP under 200 ms, CLS under 0.1
- Images in WebP or AVIF with explicit dimensions; anything below the first screen is lazy-loaded
- Fonts are loaded with
<link>plus preconnect, not via@importin CSS - No render-blocking third-party widget scripts in
<head> - Static files are served with caching and compression (gzip or brotli)
The font item comes straight from real life. On My5 fonts were pulled in with @import inside component styles, and in two places. That's two extra chained requests before the browser even starts downloading the font. Shahzod's post on how a slow site costs money goes deeper into speeding things up.
Redesigns and old URLs
The most expensive mistake I've seen doesn't happen on the old site. It happens during the move to the new one. The new site is beautiful and fast, and a month later search traffic is down by half. Because all the old URLs that had been earning rankings for years now return 404.
- Before launch, a list of every old URL was exported from the sitemap, Search Console and analytics
- Every old URL has a 301 to the closest matching new page, not to the homepage
- After launch, the Search Console “Pages” report is checked weekly for the first month
- The old sitemap wasn't simply deleted; it was replaced with the new one and resubmitted
We do the same on our own site, by the way: when the blog moved, the old article URLs were kept in a separate field and are redirected to the new ones automatically.
What to do with the findings
After an evening I usually have 15–30 items. They aren't equally important. I sort them into three piles:
- Blocks indexing. 5xx errors, a robots.txt that blocks everything, no content in the HTML, mass 404s after a redesign. Fixed first, even if other work has to stop.
- Hurts rankings. Duplicates, wrong canonicals, slow LCP, soft 404s. A plan for the next two weeks.
- Cosmetics. Long titles, a couple of images without alt text. Done along the way.
One last thing. A checklist catches problems but doesn't explain where they come from. On My5 nearly every finding was the result of a decision that once made sense: someone turned off server-side loading for speed, someone made a heading bigger by using h1. So after an audit I always write to the developers not just “what's broken” but “why it ended up this way”. Otherwise six months later the same thing shows up in a new form.