SEO for news websites: what building sites for media taught us
A news site lives by different rules than a company website. An article matters for its first day, traffic arrives in waves, and the newsroom changes the headline three times in an hour. In 2023–2024 we built several sites for media outlets and TV channels, and here is what I now build into every project like that from day one.
 Azamat AbduyaminovFounder, lead engineer
I built my first news site the same way I'd build a corporate one. A nice homepage, sections, an article page, a sitemap regenerated once a day. Everything worked until an editor asked why a story published in the morning only showed up on Google in the evening, when nobody cared about the topic anymore.
A corporate site can wait a week to get indexed. A news site needs to be in search within minutes, or the article might as well not exist.
How a news site differs from a regular one
For myself, I boiled the difference down to three things.
Indexing speed beats everything else. A story about yesterday's government meeting has a search window measured in hours. That means the sitemap must update right after publication, not via a nightly cron job.
Traffic comes from Discover and Telegram, not just search. From what we've seen, Uzbek media outlets get the lion's share of their visits from their own Telegram channels. Search and Google's Discover recommendations are a second stream that people often underestimate.
Content changes after it's published. Headlines get edited, updates get added, photos get swapped. The site has to survive all that without new URLs or duplicates.
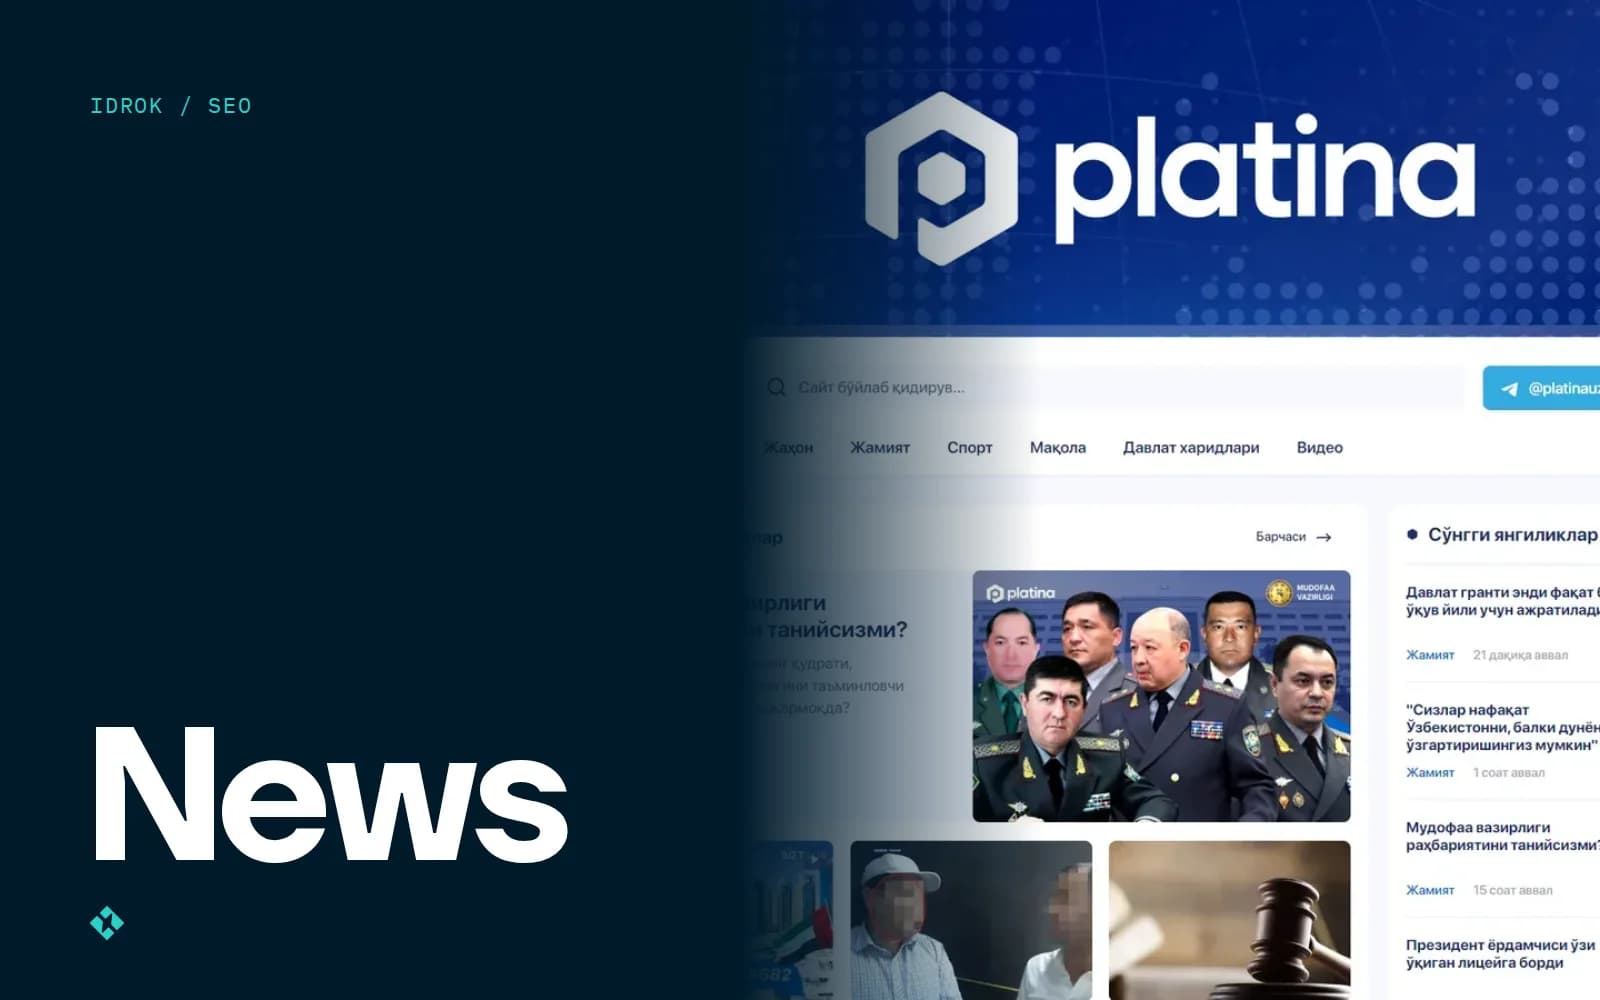
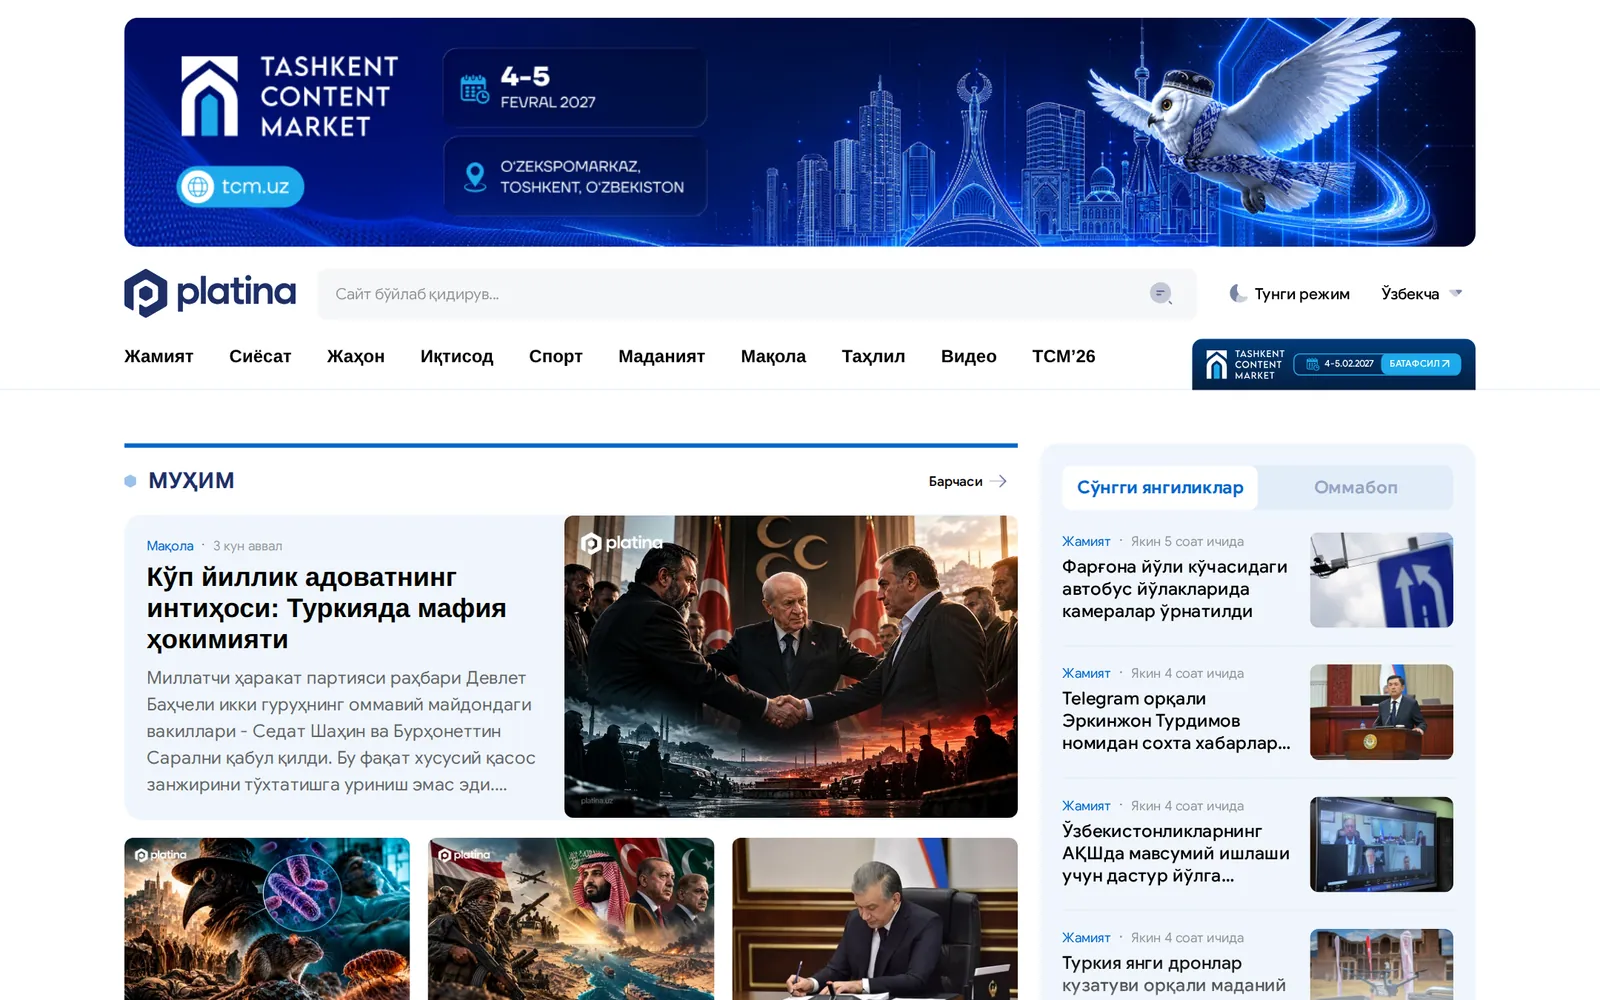
When we built Platina, a news site covering politics, the economy, science, culture and sport, we handled the logo and the UX/UI as well. So we could design the structure around these rules from the start instead of bolting them on later.
Google News, Discover and what to expect from them
Google News in 2024 works differently from five years ago. You can no longer really apply to “get into News”; selection happens automatically, based on quality and policy compliance. So the whole job comes down to making the site look like a proper publication in Google's eyes.
What that takes:
- an “About the newsroom” page with real people, contacts and editorial principles;
- an author on every article, and an author page listing their work;
- publication and update dates visible both on the page and in the markup;
- a clear separation between news, opinion and sponsored content.
Discover is a separate story. It's the recommendations feed in the Google app on Android, and for many outlets it brings more traffic than regular search. The main requirement here is technical and very simple.
Another thing people usually forget is a separate news sitemap. A regular sitemap lists every page on the site, possibly tens of thousands, and the crawler doesn't re-read it all that often. A news sitemap contains only articles from the last two days, no more than a thousand URLs, each with the publication name, language and publication time. It's small, so Google fetches it often. On bilingual sites we build one per language version: an Uzbek article and its Russian version are two publications with different headlines, not one.
NewsArticle markup without the extras
We do article markup in JSON-LD and keep it minimal but complete. Every field is filled automatically from the CMS; the newsroom doesn't type anything by hand:
{
  "@context": "https://schema.org",
  "@type": "NewsArticle",
  "headline": "Article headline up to 110 characters",
  "image": ["https://example.uz/media/16x9.webp", "https://example.uz/media/4x3.webp"],
  "datePublished": "2024-11-18T09:30:00+05:00",
  "dateModified": "2024-11-18T11:05:00+05:00",
  "author": [{ "@type": "Person", "name": "Author Name", "url": "https://example.uz/author/name" }],
  "publisher": { "@type": "Organization", "name": "Publication", "logo": { "@type": "ImageObject", "url": "https://example.uz/logo.png" } }
}
Two details people get wrong most often. Time must include the time zone, which for us is +05:00; otherwise a story that just went live shows up as “published 5 hours ago”. And dateModified should change only when the text is actually updated, not every time someone hits save in the admin. Google notices when the “updated” date jumps around with no real changes.
URLs, categories and tags
This is where I made the most mistakes, so I'll go into more detail.
An article's URL shouldn't depend on its headline
Newsrooms change headlines. If the slug is generated from the headline and rebuilt on every edit, the article gets a new URL, and the old one, already shared across Telegram channels, returns a 404.
The scheme we settled on: the URL contains a numeric id plus a slug, for example /news/48213-tashkentda-yangi-metro-bekati. The site looks the article up by id. If the slug in the request doesn't match the current one, we return a 301 to the correct URL. The headline can change as often as the editors like, and links never break.
Categories vs tags
| Categories | Tags | |
|---|---|---|
| How many | 5–15, rarely change | hundreds to thousands |
| Who creates them | defined when the site is designed | the journalist, at publication time |
| Index them? | yes, these are strong pages | only tags with 5+ articles |
| Purpose | navigation, site structure | linking articles on one topic |
The main problem with tags is that journalists create them on the fly. A year later the site has three thousand tags, half of them with a single article, and “Ташкент”, “ташкент” and “Toshkent” live as three separate pages. Google sees thousands of thin pages. We noindex tags with fewer than five articles and give the newsroom a way to merge duplicates in the admin.
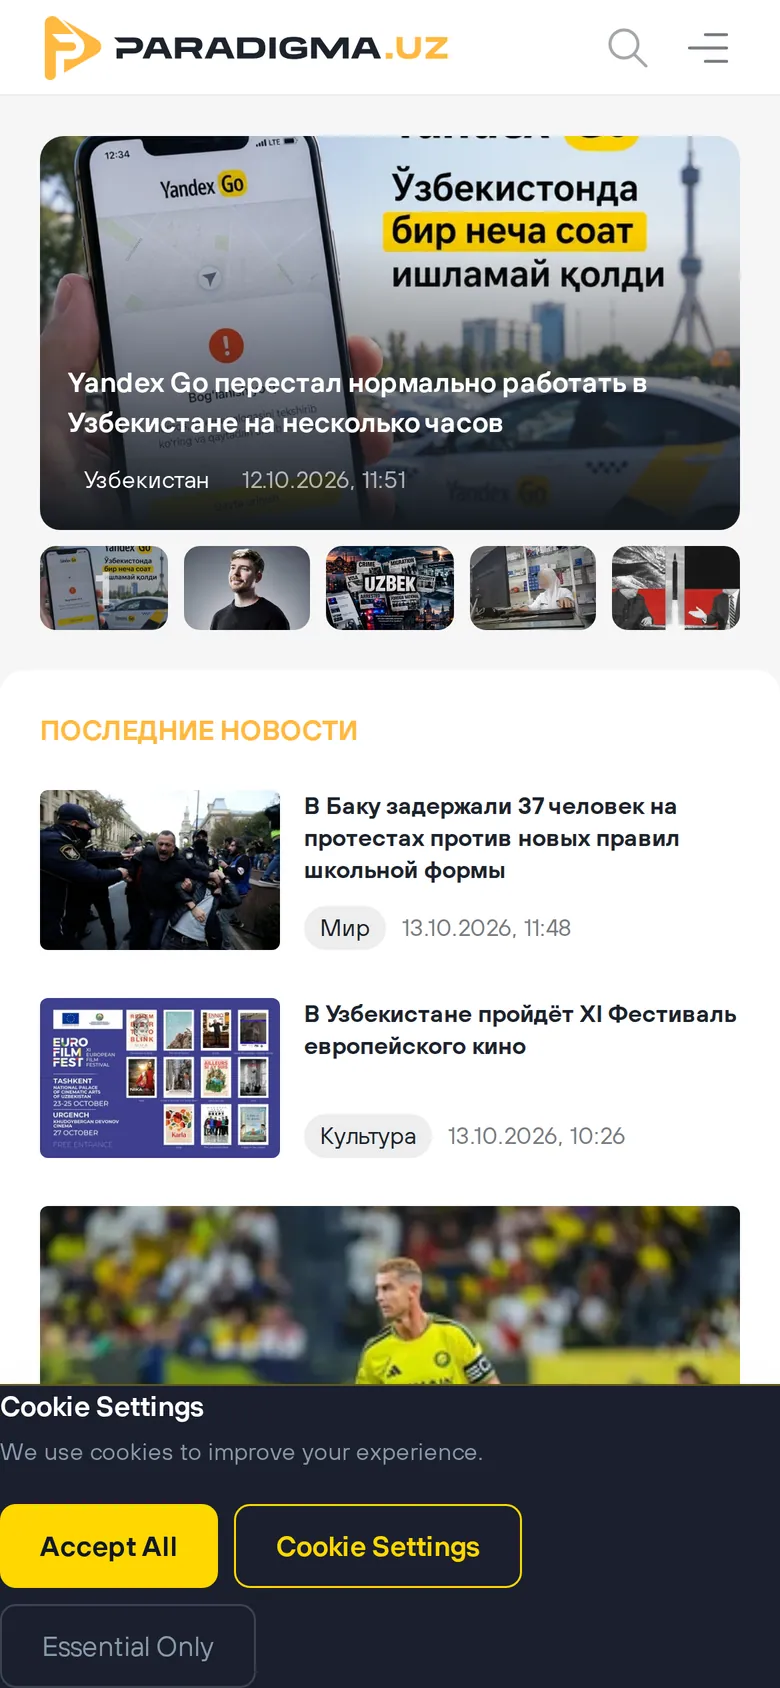
On Paradigma things are even more interesting, because besides news it has documentaries and podcasts. Those are different content types, and mixing them in one feed with one kind of markup would be a mistake. Video and audio deserve their own sections and their own markup.
When everyone reads the same story at once
A news site doesn't go down on an ordinary day. It goes down when a big Telegram channel reposts an important story and ten minutes bring in as many people as a normal week.
“Load doesn't come from the number of articles. It comes from one article that everyone opens at the same moment. So the first thing to cache is the article page, not the homepage.”
What we build in for that:
- the article page is server-rendered (we usually use Nuxt 3) and cached at the nginx level for at least 30–60 seconds, which is enough to turn a thousand simultaneous requests into one request to the backend;
- publishing or editing an article purges that page's cache, so a corrected headline appears immediately;
- images are served as resized WebP, not 6 MB originals straight from the photographer's phone;
- the view counter is written asynchronously, not in the same request that serves the page.
On My5, the portal of the Mening Yurtim TV channel, the load pattern is similar: the spike comes right after a broadcast, when people search for the episode or show they've just watched.
You don't need AMP anymore
A few years ago you couldn't get into Google's Top Stories carousel without AMP. That requirement was dropped in 2021, and getting in now depends on the usual page speed and quality signals.
We don't build AMP on new projects. Maintaining a second version of every page with its own restrictions is expensive, and the benefit is gone. If you have an old site with AMP, remove it carefully: 301 every AMP URL to its regular counterpart, or you'll lose the links that have built up pointing at them.
If I were starting a news site from scratch today, I wouldn't spend the first money on the homepage design. I'd spend it on three things: an instantly updated sitemap, stable article URLs and caching for the article page. The rest can be tuned later. We help with this as part of our SEO service, and Murodjon wrote about why the structure of a news homepage is a UX question rather than a matter of looks in his post on UX/UI design.